Ant Group Open-Sources Ming-3.0-tts Speech Models Under MIT License
The MIT-licensed family includes a 0.5B dense generator and a 7.9B MoE variant with fine-grained voice design, dialect synthesis, and paralinguistic controls.
In short
- Ant Group's inclusionAI team has released inference code and weights for Ming-3.0-tts-0.5b and Ming-3.0-tts-tiny under the permissive MIT license.
- The models support zero-shot voice cloning, voice design from natural language prompts, 14 inline paralinguistic tags, and two Chinese dialects.
- On the independent Artificial Analysis leaderboards, Ming-3.0-tts ranked first among open-weights systems on Controlled Voice, while Ant Group's project documentation states it ranked first overall on Pronunciation Robustness.
- The tiny variant introduces multi-speaker conversation modeling for podcast-style generation using an MoE architecture with 1.3 billion active parameters.
Ant Group's inclusionAI team has made its Ming-3.0-tts speech generation model family publicly available under an open-source MIT license, releasing code, cookbooks, and weights across GitHub and Hugging Face. The release provides small-scale models configured to give developers granular control over speech attributes, paralinguistic vocalizations, and voice identity.
While checkpoint files first appeared in late September 2026, the complete runnable release arrived on October 19, 2026, when inclusionAI published inference pipelines, Docker configurations, and verification scripts according to OrcaRouter's release analysis. The release accompanies a broader push into audio intelligence by Ant Group, complementing the 126-billion-parameter Ming-3.0-audio-flash multimodal model published in September 2026.
Two Model Sizes and a Shared Architecture
The Ming-3.0-tts release includes two distinct speech generators that share a common synthesis design: a language model backbone conditioned on text and task tokens, paired with a diffusion-transformer (DiT) patch head, an audio tokenizer, and an ONNX-based CAM++ speaker embedding extractor. Output of 44.1 kHz audio is confirmed for the 0.5b checkpoint.
The smaller checkpoint, Ming-3.0-tts-0.5b, uses a dense architecture built on a 0.5-billion-parameter language backbone. While the backbone is compact, the complete Hugging Face distribution bundles the DiT head, audio VAE, and tokenizers into a single 2.96 GB file, as detailed in OrcaRouter's architectural breakdown. Inference for the 0.5b model has been tested on NVIDIA H800 and H20 GPUs with PyTorch scaled dot-product attention fallback.
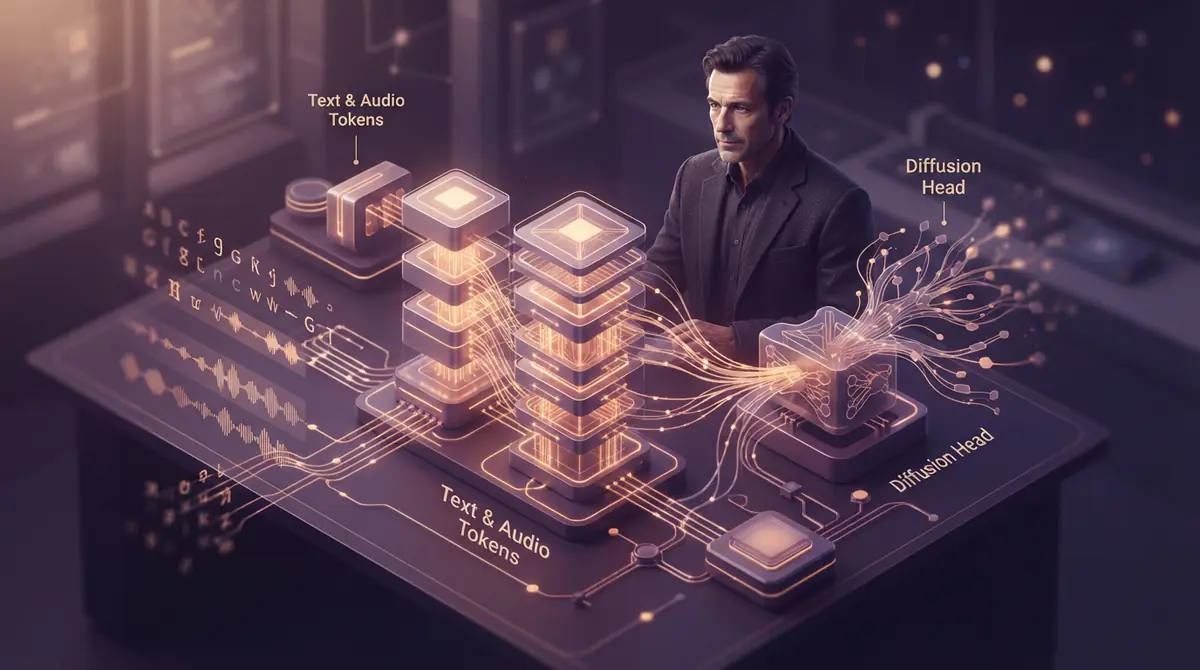
The second checkpoint, Ming-3.0-tts-tiny, uses a Mixture-of-Experts (MoE) design built on Ant Group's Ling V3 foundation. It contains 7.9 billion total parameters while activating approximately 1.3 billion parameters per token. The tiny variant uses sharded weights totaling roughly 18 GB and requires a pinned runtime environment using Python 3.10.15 and PyTorch 2.7.1, according to technical documentation on GitHub.
Controlled Voice Design, Dialects, and Paralinguistics
Ming-3.0-tts separates speech generation into distinct, mutually exclusive task modes. Instead of combining arbitrary control tags, developers specify a targeted task in the Python API or command-line interface.
For voice identity, the models support zero-shot cloning from a short reference audio clip, selection from a catalog of over 100 Chinese and five English built-in voices, or text-based voice design. Under the voice design task, developers generate a distinct speaker without audio reference by submitting a natural-language description of tone, gender, pacing, and vocal texture. Delivery can also be guided via natural-language instructions in a freeform task mode.
For expressive speech, the models implement 14 inline paralinguistic tags in Chinese and English text, enabling developers to prompt sighs, laughter, coughing, breathing, and hesitation. The models support seven languages: Chinese, English, German, Spanish, French, Korean, and Japanese. When supplied with a dialect reference clip, both models can synthesize Sichuanese and Cantonese.
The larger Ming-3.0-tts-tiny checkpoint includes an exclusive podcast task mode, as reported by Pandaily. This mode accepts scripted dialogue tagged with speaker identifiers and individual audio references, generating multi-speaker conversations in a single generation pass.
Benchmark Results and Independent Leaderboard Rankings
Ant Group's release coincided with independent evaluations on the Artificial Analysis text-to-speech arena on October 19, 2026. Evaluating the Ming-3.0-tts-0.5b checkpoint, Artificial Analysis ranked the model first among open-weights systems on its Controlled Voice leaderboard with an Elo rating of 1069, placing it 14th overall.
On the Provider Voice leaderboard, where models use native built-in voices, Ming-3.0-tts scored an Elo of 1188, ranking third among open-weights releases behind Fish Audio Drama 3 Preview and Breeze TTS 2. On Artificial Analysis hardware, the model achieved a median speed of 42.1 characters per second. Ant Group's repository also notes the model ranked first overall on Pronunciation Robustness with 93.2% of highlighted spans judged correct by human evaluators, leading the shorthand expansion and sequence fidelity sub-categories.
In Ant Group's published Seed-TTS benchmarks, the 0.5b model achieved a 0.800% word error rate (WER) on Chinese and 1.584% on English, while the tiny model recorded 0.820% on Chinese and 1.666% on English. These figures trailed competitor systems in the same comparison table: CosyVoice3-1.5B posted a lower Chinese WER of 0.710%, and Qwen3-TTS-12Hz-1.7B-Base posted a lower English WER of 1.240%. On NVBench evaluations, Ant Group reported state-of-the-art results across all six single-tag paralinguistic metrics.
Known Weaknesses and Deployment Requirements
The project documentation explicitly lists several technical trade-offs. Pitch adjustments were identified in model cards as the least accurate of the attribute controls, and emotion steering degrades when the input text lacks natural emotional indicators. While the models lead in paralinguistic single-tag benchmarks, complex sentences with multiple inline tags can exhibit instability.
A clear performance discrepancy appears in Korean synthesis. According to OrcaRouter's comparative analysis, Ming-3.0-tts-tiny exhibits a 6.000% character error rate on Korean test sets, compared to 1.728% for the smaller 0.5b dense model. The team also noted that speaker similarity in newly added non-primary languages often misses top-three benchmark marks.
Local deployment requires specific tooling. By default, text normalization for numbers, units, and dates relies on finite-state transducer grammars powered by pynini version 2.1.6, which must be installed from conda-forge or bypassed using an optional --no_text_normalization flag. For multi-model production serving, the models can be deployed through SGLang-Omni, which exposes an OpenAI-compatible audio API, while vLLM-Omni accelerated inference is already checked off as completed on the GitHub repository roadmap, leaving only the technical report pending.
Questions people ask
What license governs the Ming-3.0-tts model family?
Ming-3.0-tts is released under the open-source MIT license for both model weights and code. Ant Group includes a usage disclaimer requesting that developers avoid impersonating individuals without consent and label synthetic audio.
What is the difference between Ming-3.0-tts-0.5b and Ming-3.0-tts-tiny?
Ming-3.0-tts-0.5b is a dense model built on a 0.5B language backbone designed for lightweight inference. Ming-3.0-tts-tiny is a Mixture-of-Experts model built on Ling V3 with 7.9B total parameters (1.3B active per token) that adds multi-speaker podcast generation.
What languages and dialects are supported?
The models support Chinese, English, German, Spanish, French, Korean, and Japanese, as well as Sichuanese and Cantonese regional Chinese dialects when provided with a dialect reference clip.
Can Ming-3.0-tts be deployed through standard inference servers?
Yes. Ming-3.0-tts can be served locally via standalone CLI and Python scripts, and it is supported by SGLang-Omni to expose OpenAI-compatible speech synthesis endpoints on a single GPU. vLLM-Omni accelerated inference is already checked off as completed on the GitHub roadmap, leaving only the technical report pending.
Sources
- inclusionAI/Ming-3.0-audio-flashHugging Face, Sep 3, 2026, official source
- inclusionAI/Ming-3.0-ttsGitHub, Oct 19, 2026, official source
- inclusionAI/Ming-3.0-tts-tinyHugging Face, Sep 22, 2026, official source
- Ant Group Open-Sources Ming-3.0-tts, Small Speech Models With Voice Design and Fine Controlpandaily.com, Oct 19, 2026
- Ming-3.0-tts-0.5B Shipped Twice, and Ant Group Announced NeitherOrcaRouter, Oct 19, 2026
- Ming-3.0-tts-tiny vs. Sesame-Preview: Ein herunterladbarer Checkpoint gegen eine Stimme, die man nicht aufrufen kannOrcaRouter, Oct 19, 2026
How this story was made: the newsroom picked it up from Reddit, Google News and pandaily.com, gathered the full text of the sources above, and drafted it with AI assistance. Every factual claim was then checked against those sources before publishing (34 claims checked). Illustrations marked as AI-generated are not photographs. Spotted an error? Tell us.
Published October 20, 2026 at 04:11 UTC